Odaseva Zero-Copy
Data Integration
for Microsoft Fabric

The Data Gap for Agentic AI
Native OneLake Integration
Eliminate data replication and complex ETL. Odaseva delivers your Salesforce data directly into OneLake in native Delta Lake tables. Empower business analysts, data scientists, and engineers to access a single, unified source of customer truth.
Frictionless Data Ops
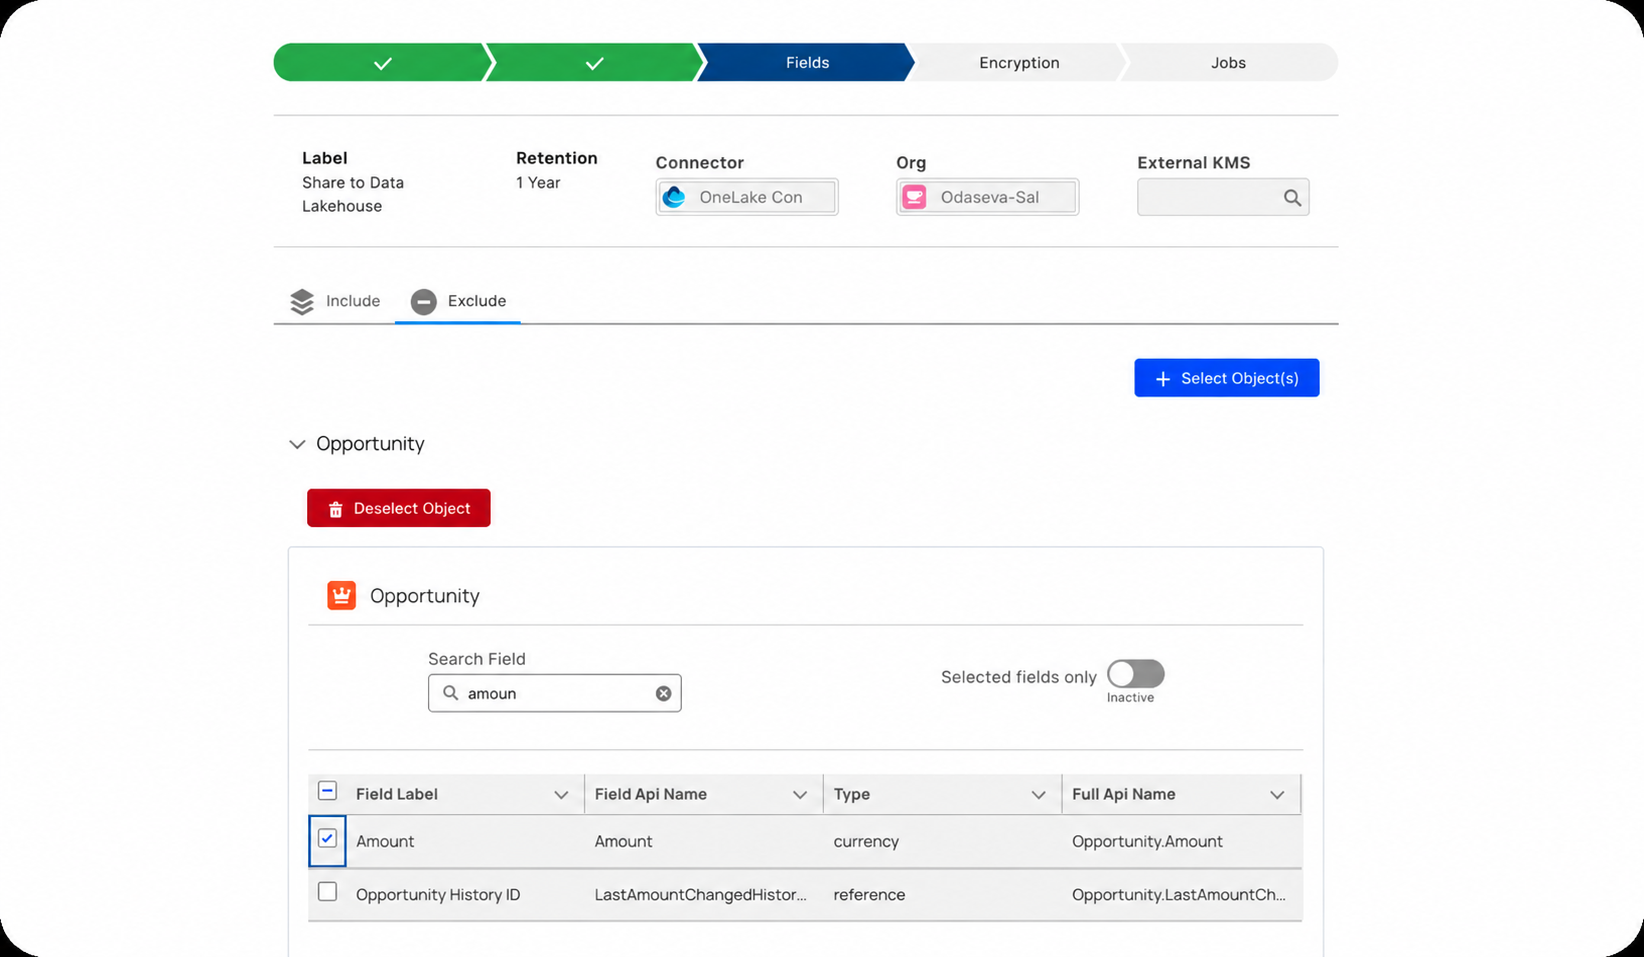
Reclaim engineering capacity with an enterprise-grade managed service that automatically handles complex Salesforce object relationships, API optimization, history tracking, and schema drift within your Fabric Lakehouse.
Complete & Activated Customer Context
Feed your Microsoft Copilots and AI models with the full picture. By reusing your secure backup and archive streams, we can unlock your entire Salesforce history and deep archives without impacting production CRM performance.
Unified Governance & Security
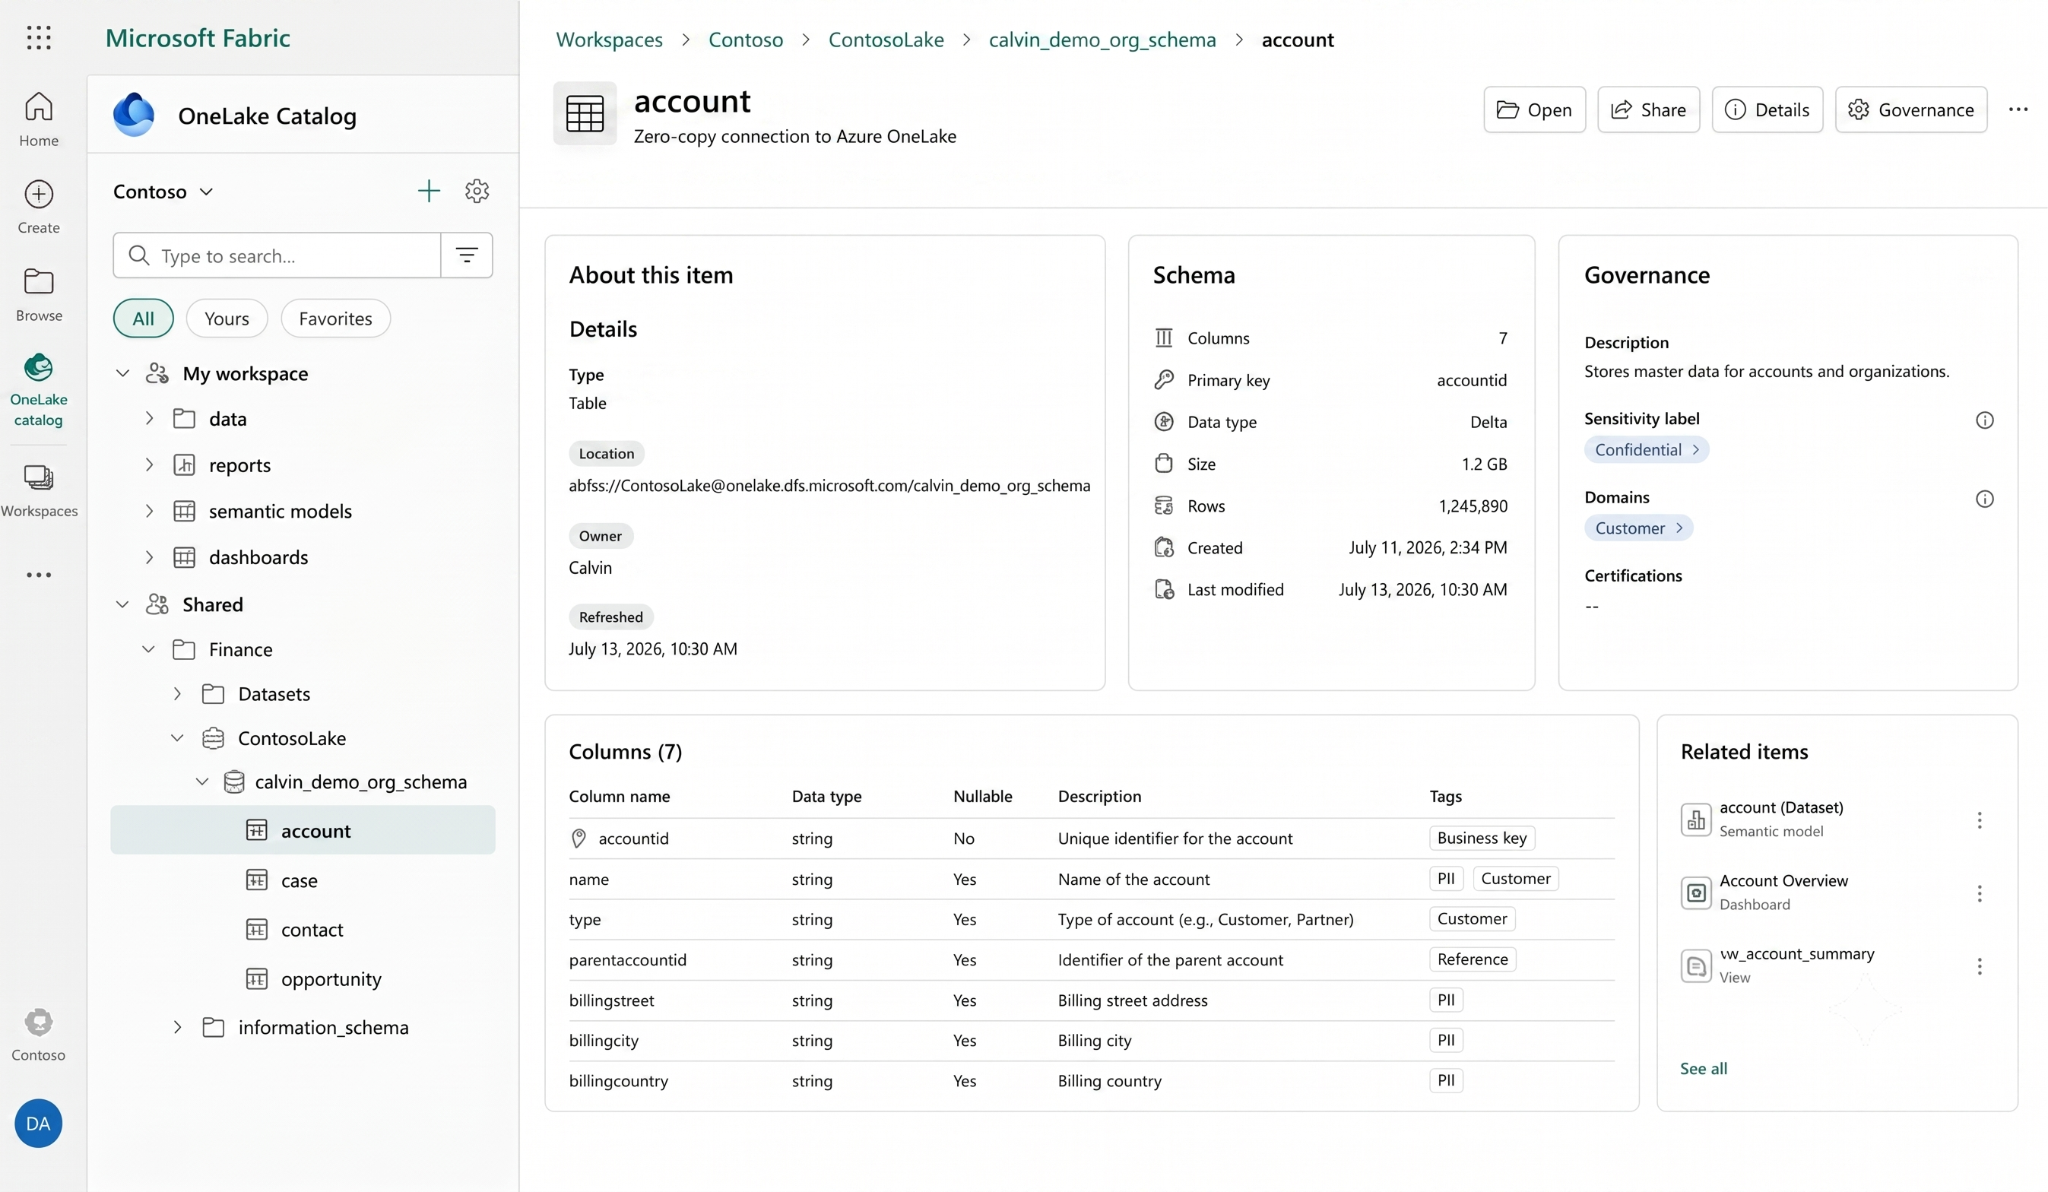
Secure your CRM data without locking it down. Maintain control over your Salesforce data with end-to-end security while aligning with OneLake Catalog and Microsoft Purview.
Why Odaseva Zero-Copy Data Sharing for MS Fabric?
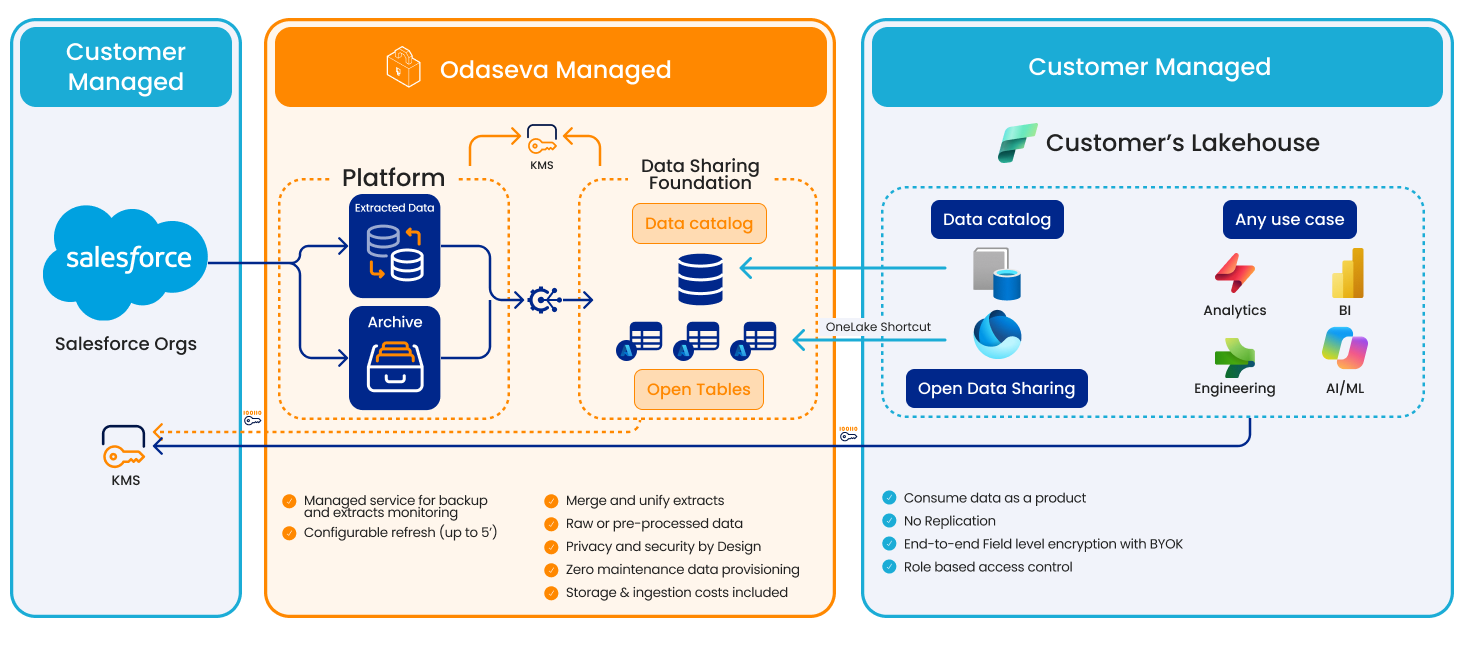

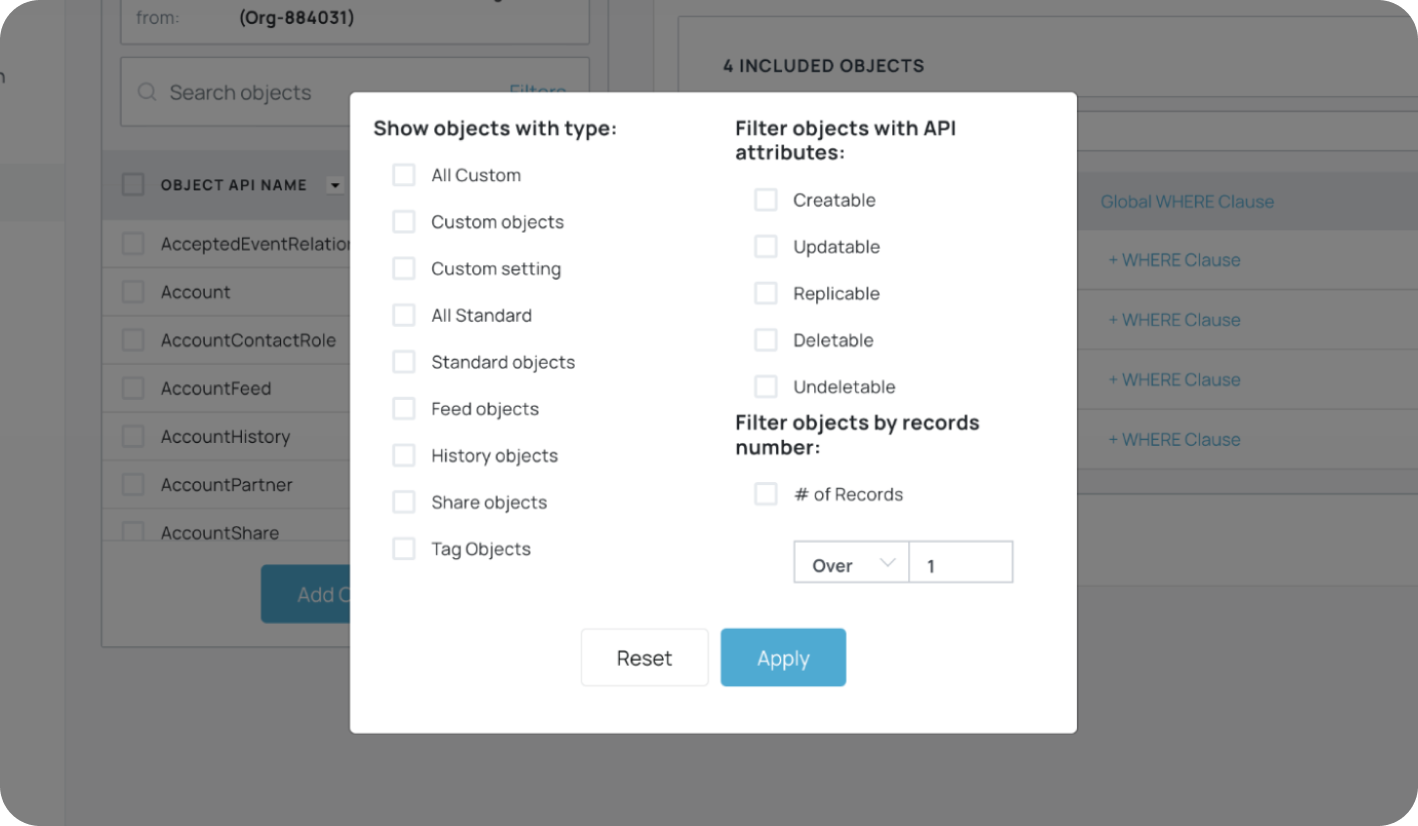
Bypass your data volume limits. Engineered for large-scale global Orgs, our zero-copy integration provides instantaneous visibility into billions of rows of customer history without triggering Salesforce API throttling or infrastructure limits.
Stop paying unpredictable, usage-dependent egress and compute taxes. Our simple, predictable managed service activates your entire Salesforce data scope for enterprise reporting and Azure AI.
By safely repurposing your continuous data protection streams into live, virtualized OneLake datasets, we eliminate the extraction overhead and performance issues typically imposed on your live Salesforce instance.
Offload legacy historical records to keep Salesforce lean while ensuring your Fabric Lakehouse retains the complete historical context required for compliance, high-fidelity trend analysis and grounding autonomous agents.
Personas
Rethink Your Data Architecture to Power Next-Gen Data Products
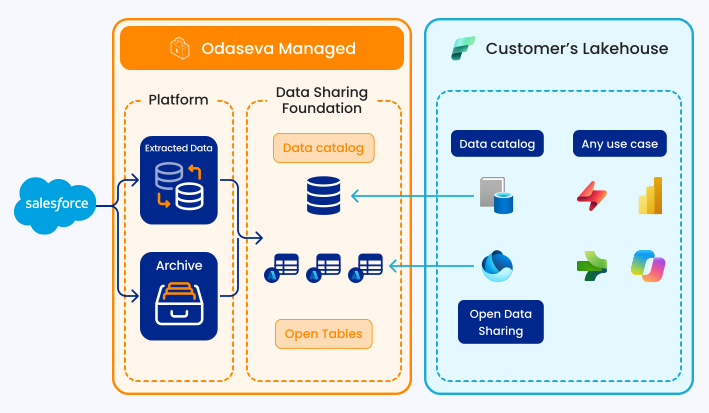
Fuel Microsoft Fabric with near-real-time, complete customer context using zero-copy data sharing, without the infrastructure and governance overhead.
Reclaim Engineering Time, Create Greater Value
Escape from maintaining fragile ETL data pipelines or manual extractions, and focus instead on delivering immediate business by consuming always on, self-managed Delta tables seamlessly integrated within your Fabric workspaces.
Gain Complete Data Autonomy for Faster Model Grounding
Instantly access comprehensive Salesforce datasets and histories directly from your Fabric notebooks and Azure OpenAI services, avoiding the need for custom pipeline development.
Scale AI, Reduce the Data Debt
Remove frictions to connect data to business impact and fuel the Agentic Enterprise at scale.

Activate Salesforce Data for AI & BI, Instantly
Break the CRM walled garden by making Salesforce data a first-class citizen, directly tying your most valuable CRM assets to Power BI, Copilot and Fabric Data Science.
Centralize Trust Across Cross-Cloud Boundaries
Establish a controlled accessibility into customer data. Maintain precise end-to-end governance with centralized security policies natively aligned with Microsoft Purview and Fabric workspace security settings.
FAQs

While traditional ETL tools require constant data replication, Odaseva redefines how Salesforce integrates with Microsoft Fabric. Rather than forcing data teams to struggle with Salesforce API rate limits, tedious schema mapping, and frequent schema drift, we treat Salesforce data as a fully managed, pre-optimized asset.
By securely leveraging your existing backup and data protection streams, we surface compliant data directly to your Fabric environment. This eliminates the burden of infrastructure maintenance by handling complex relational data models and automated schema evolution completely in the background. Although downstream custom data engineering can still be executed using Microsoft Data Factory, Power Query or alternative data transformation tools, the tedious effort of managing Salesforce data ingestion is entirely eliminated.
Bottlenecks often occur during massive extraction loops on the SaaS source side. Leveraging our years of experience in extracting, securing, and repurposing very large volumes of Salesforce data, Odaseva decouples the ingestion layer from consumer access by pre-packaging datasets into highly optimized Delta Lake formats within a secure, high-performance repository. This approach ensures that even global organizations tracking billions of database rows can have their analytical reporting layers and automated model runs in Fabric query data instantly, without structural degradation or latency bottlenecks.
The integration is built directly on native Delta Lake format standards. Odaseva automatically converts your Salesforce data structures into fully optimized, schema-mapped Delta-Parquet tables, and exposes them through open Delta Sharing protocols.
Instead of executing a heavy copy-and-paste job across platforms, Microsoft Fabric's engines connect directly to this high-performance data layer. Fabric queries the data in-place on demand, treating your Salesforce records as first-class, native Delta tables inside your workspace. This bypasses the need for scheduling, monitoring, or running traditional pipeline plumbing altogether.
If you are already using Odaseva Backup and Restore, no, and this is a fundamental advantage of our approach. Because we uniquely reuse your existing data protection streams, the zero-copy activation process triggers no additional API calls against your live Salesforce production Org. Your analytical workloads inside your data lake run completely out-of-band, preserving 100% of your operational CRM capacity.
If you do not use Odaseva Backup and Restore, the impact is negligible. Odaseva was built from the ground up to handle Salesforce data at extreme enterprise scale. Recognized across the industry for our efficiency, our platform uses highly optimized API extraction methods designed to pull massive volumes of data while minimizing Salesforce resource consumption.
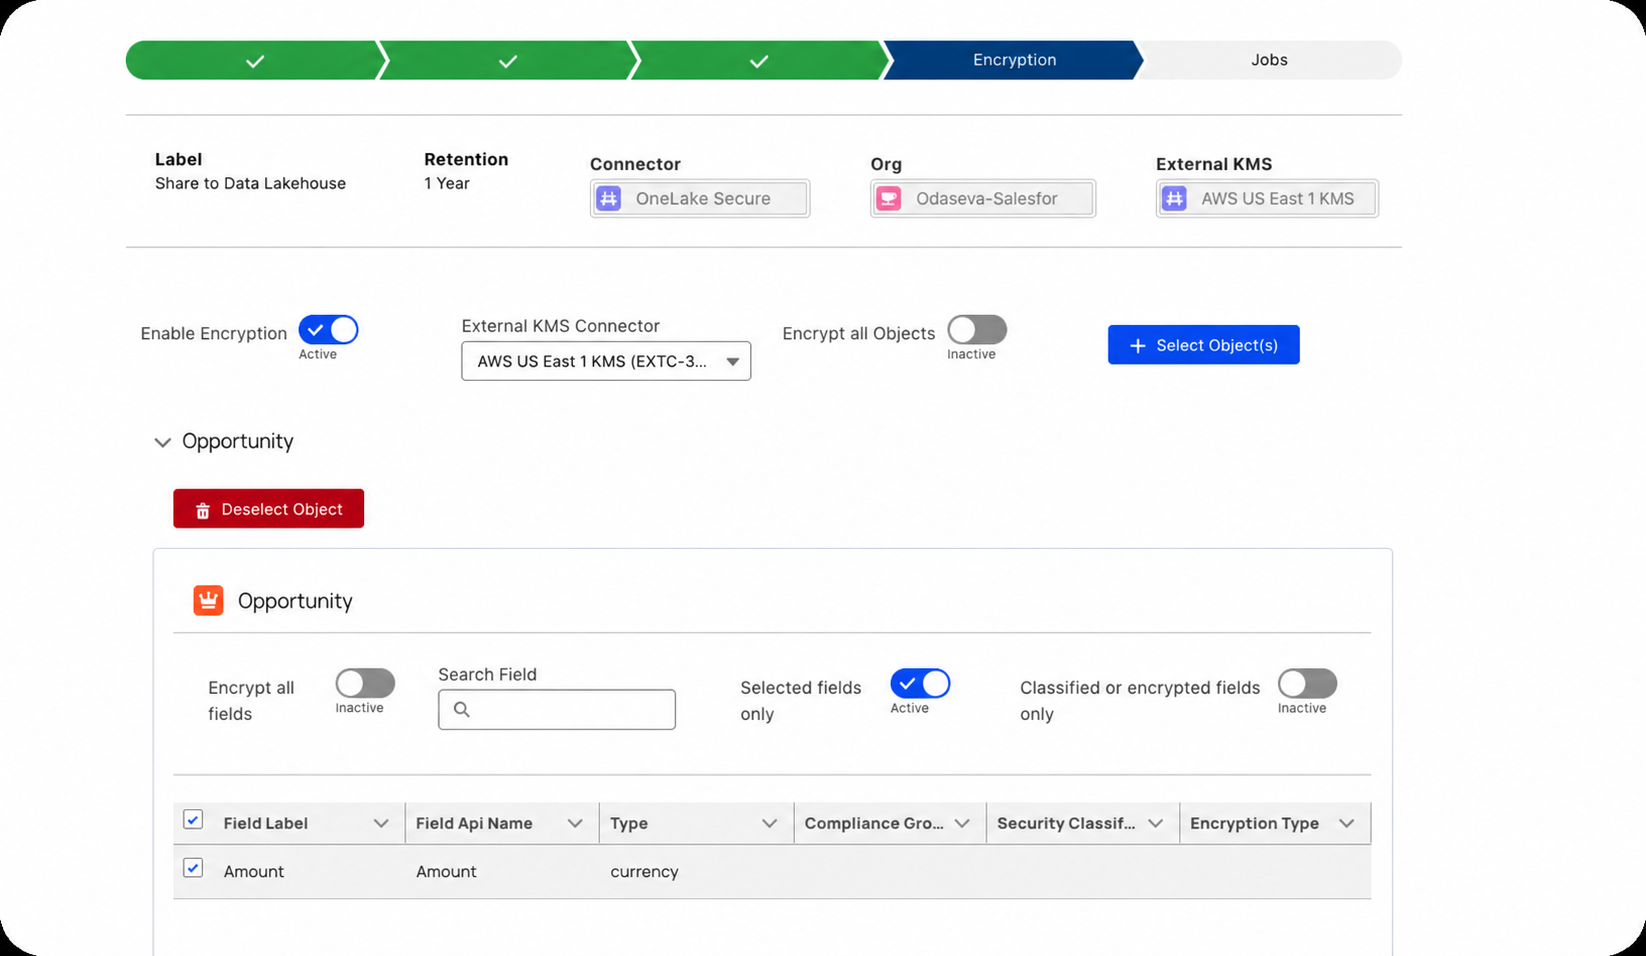
Odaseva’s commitment to data security exceeds the requirements of even the most complex, highly regulated businesses in the world. It’s a major reason why leading enterprises trust Odaseva. Data remains privacy-compliant through end-to-end encryption with customer managed keys for your most critical datasets, providing absolute sovereignty over sensitive fields. For broader organizational needs, data masking can be applied before data sharing.
Because Odaseva is a Salesforce data resilience platform, handling API limits, schema drift, and SaaS outages is our core competency, not an afterthought.
Our architecture is designed to automatically detect throttling, handle retries, resolve silent sync failures, and resume extraction without data loss. Since we deliver Data-as-a-Product, monitoring and resolving these interruptions are part of our managed services. If a disruption occurs, our team and automated systems handle the resolution and backfilling behind the scenes, ensuring you can consume reliable data without having to debug failed jobs.
Key resources
Empowering Scalable, AI-ready Data Ecosystems with Odaseva Data Edge
Modern Architecture for Data at Speed and High Availability

3 Steps to Secure Your Data in an AI-Automated World


