Odaseva Zero Copy Data Sharing for Amazon Redshift

Instant Data Activation
Go from Salesforce data to Redshift insights in minutes. Our managed service automates the underlying orchestration, autonomously eliminating pipeline friction, and schema drift so your analysts can move at the speed of business without the operational overhead.
AI-Ready Data Products for SageMaker
Power Redshift ML and SageMaker Canvas with complete, historical data. By sharing the full depth and breadth of your Salesforce data, you provide the critical context required for deep analytics and trusted AI.
Enterprise-Grade Robustness
Scale to billions of records with an unbreakable architecture engineered for the world’s largest Orgs. We deliver high-volume data sharing to AWS without any impact on your Salesforce production performance and resource usage.
AWS-Native Security & Trust
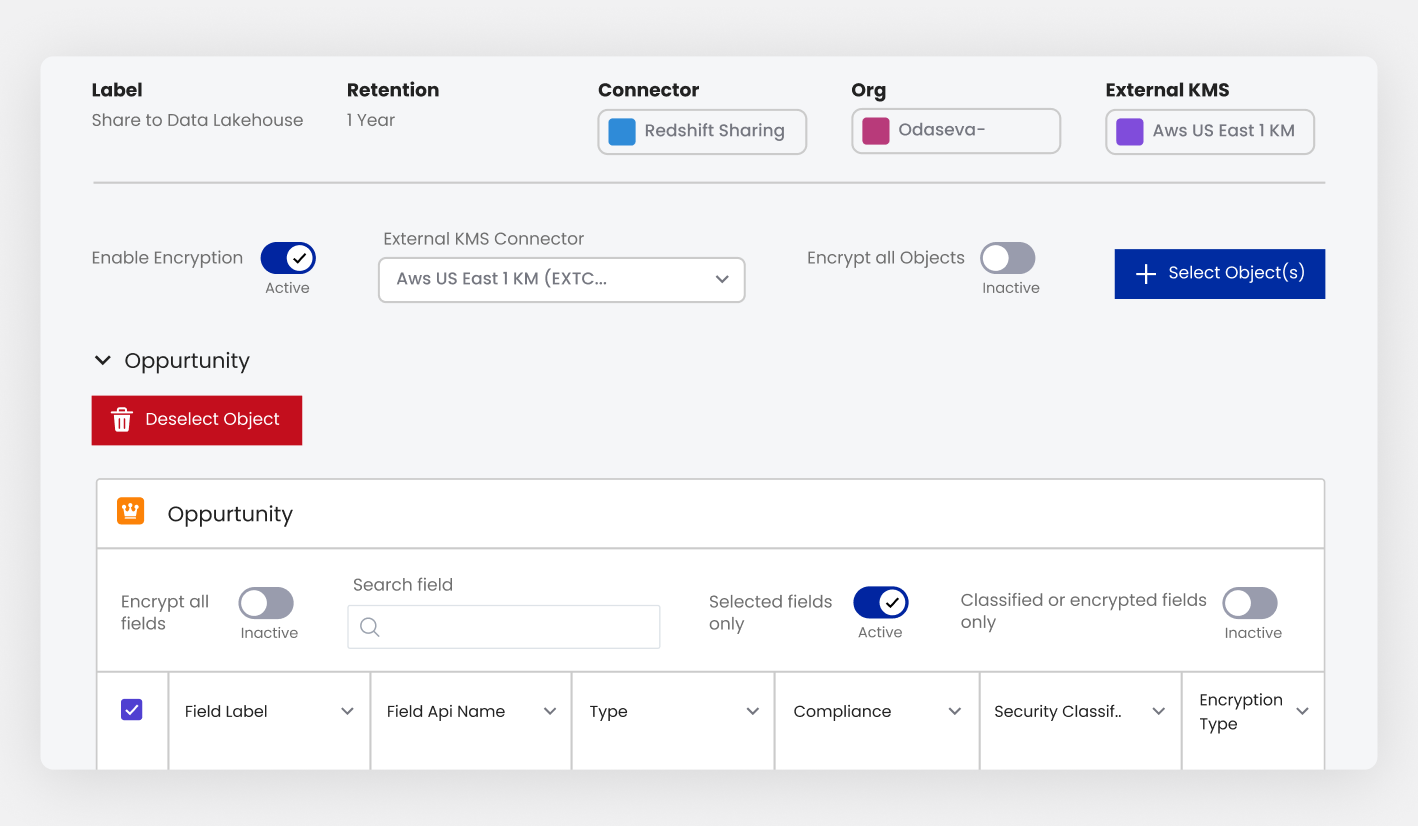
Share data via a secure AWS backbone. Use your own AWS KMS keys for end-to-end encryption while choosing from multiple AWS regions to meet flexible residency requirements.
Why Odaseva Zero Copy Data Sharing for Redshift?
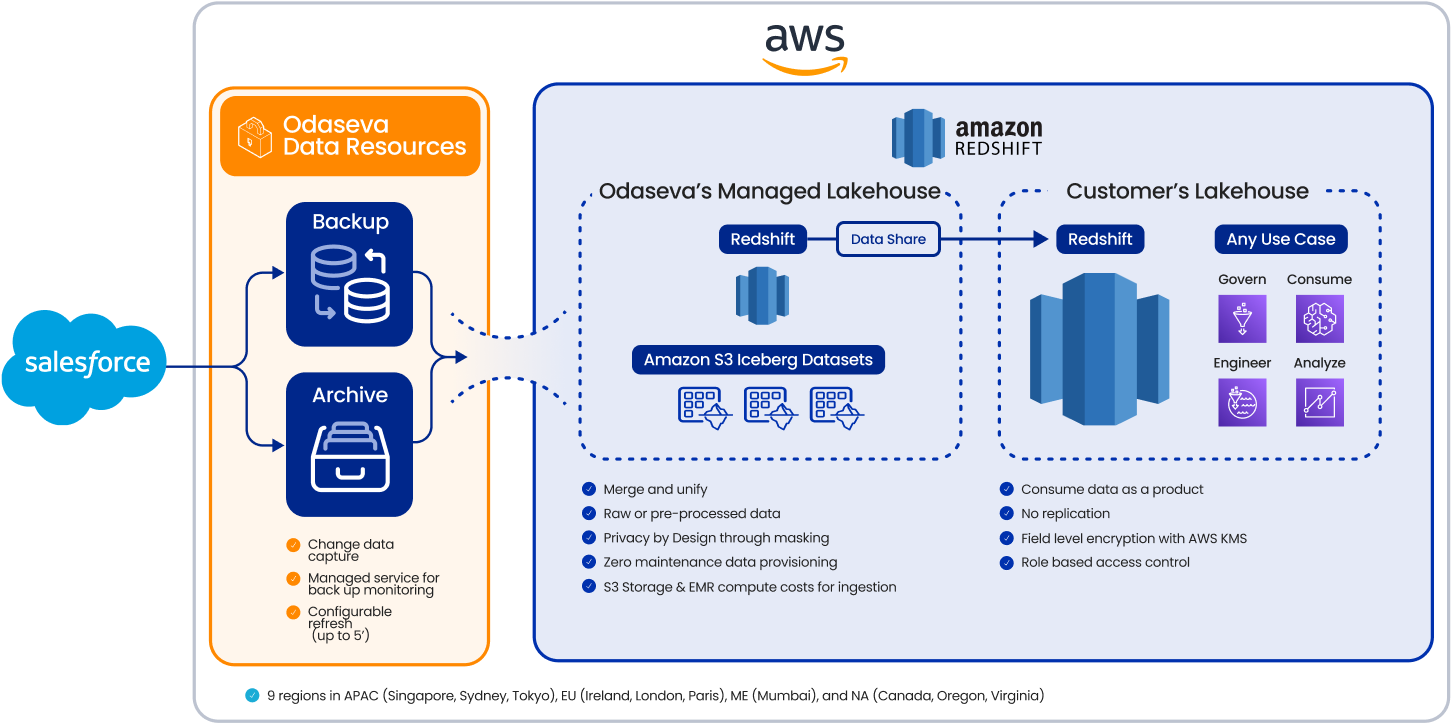

Bypass restrictive and resource intensive API quotas. Odaseva takes a different path by activating data already extracted from your backup snapshots directly into your AWS AI engine.
Stop paying data tax. One fixed fee activates your entire Salesforce scope for AI and analytics.
Eliminate redundant movement by activating Salesforce data once for secure reuse across AWS analytics, apps, and AI agents.
Turn dormant archives into insights. A combined approach for archiving and sharing keeps your production Salesforce Org lean and high-performing, while unlocking the full historical context in Redshift for trusted AI.
Personas
Revisit Your Data Architecture for Next-Gen Data Products
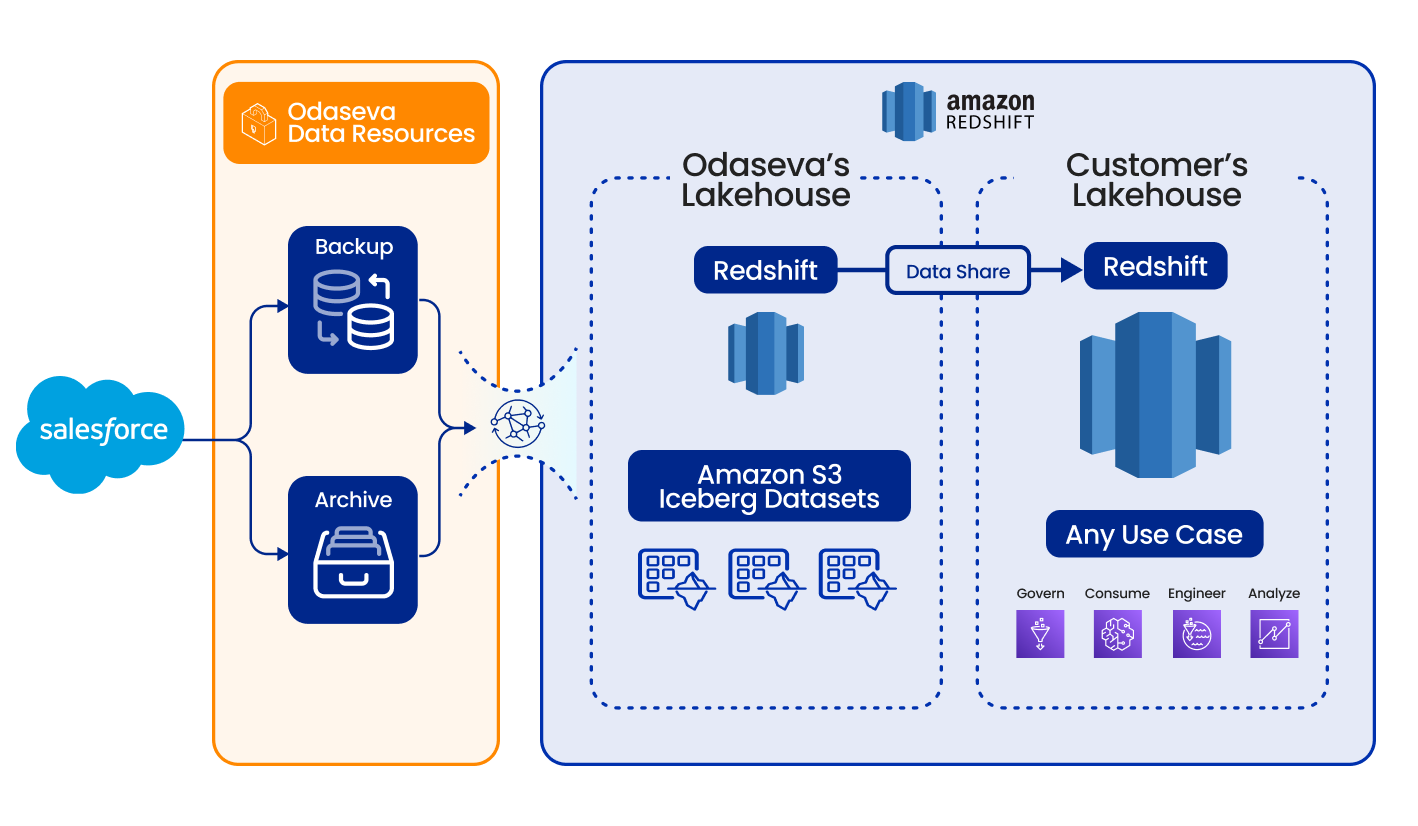
Activate your customer data on AWS using open standards. We deliver Salesforce Data-as-a-Service via Apache Iceberg and Redshift Spectrum.
Reclaim Time, Build More Value
Reclaim 40% of the time lost to pipeline maintenance. Leverage a managed service that handles the underlying orchestration autonomously, and focus on fueling AI with customer context
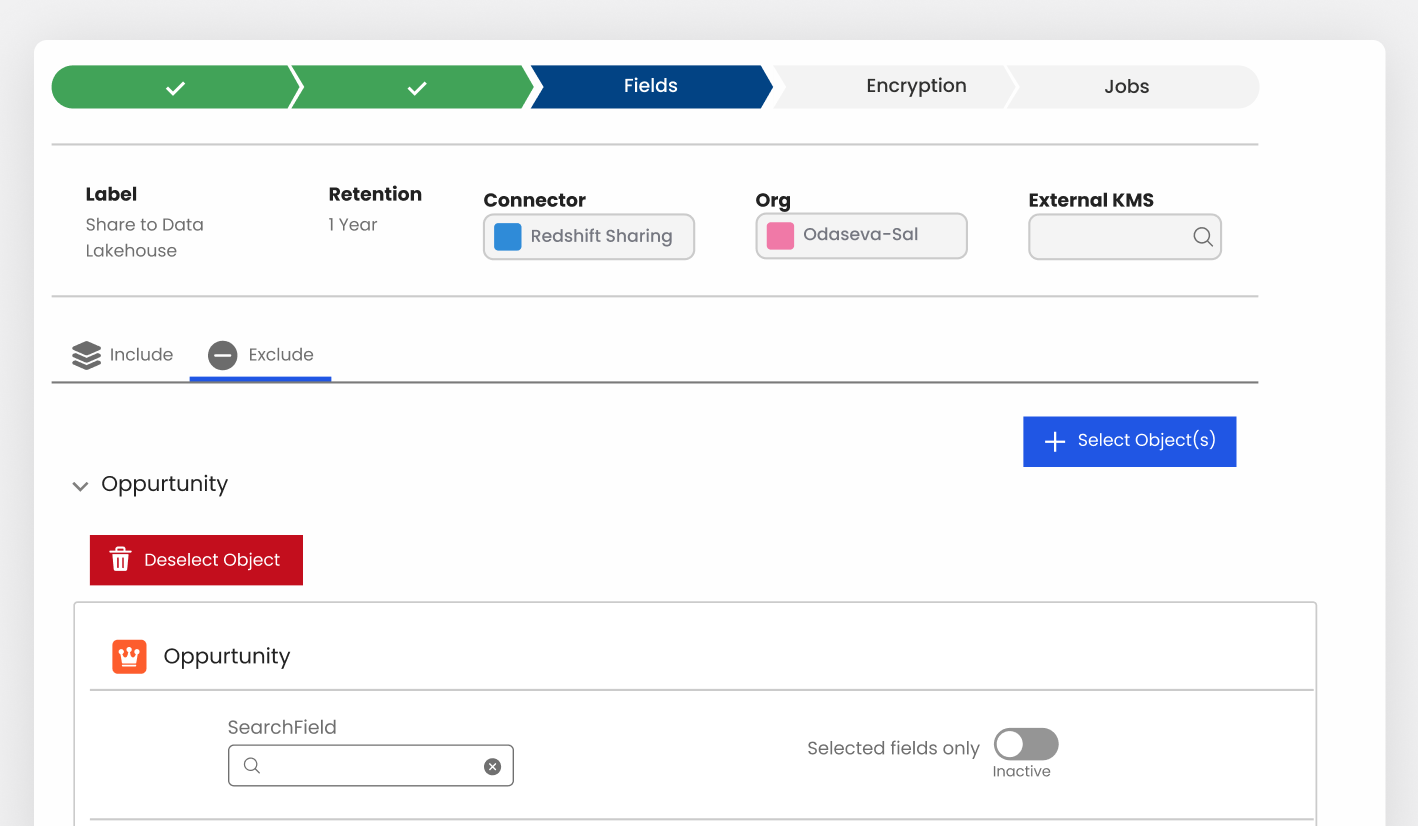
Consume Data Products in SageMaker
Gain instant, self-service access to customer data without dependency on IT teams. Ground your Redshift ML models and SageMaker Canvas workflows with customer context for more accurate predictions and customer experiences.
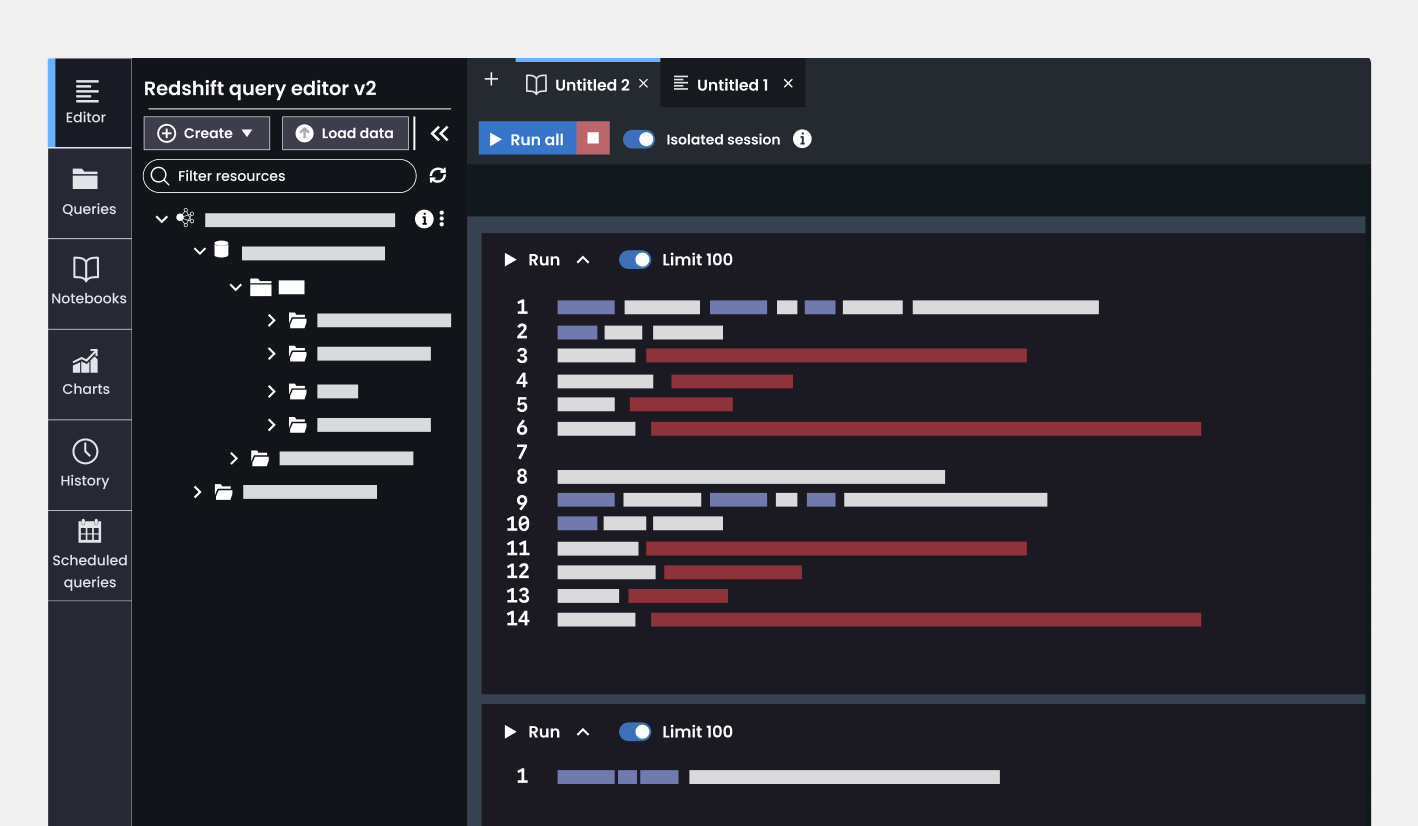
Accelerate AI Maturity with Robust Data Foundations.
Shorten your time-to-market for AI innovation by months with a future-proof data platform that removes CRM integration friction and reduces technical debt.
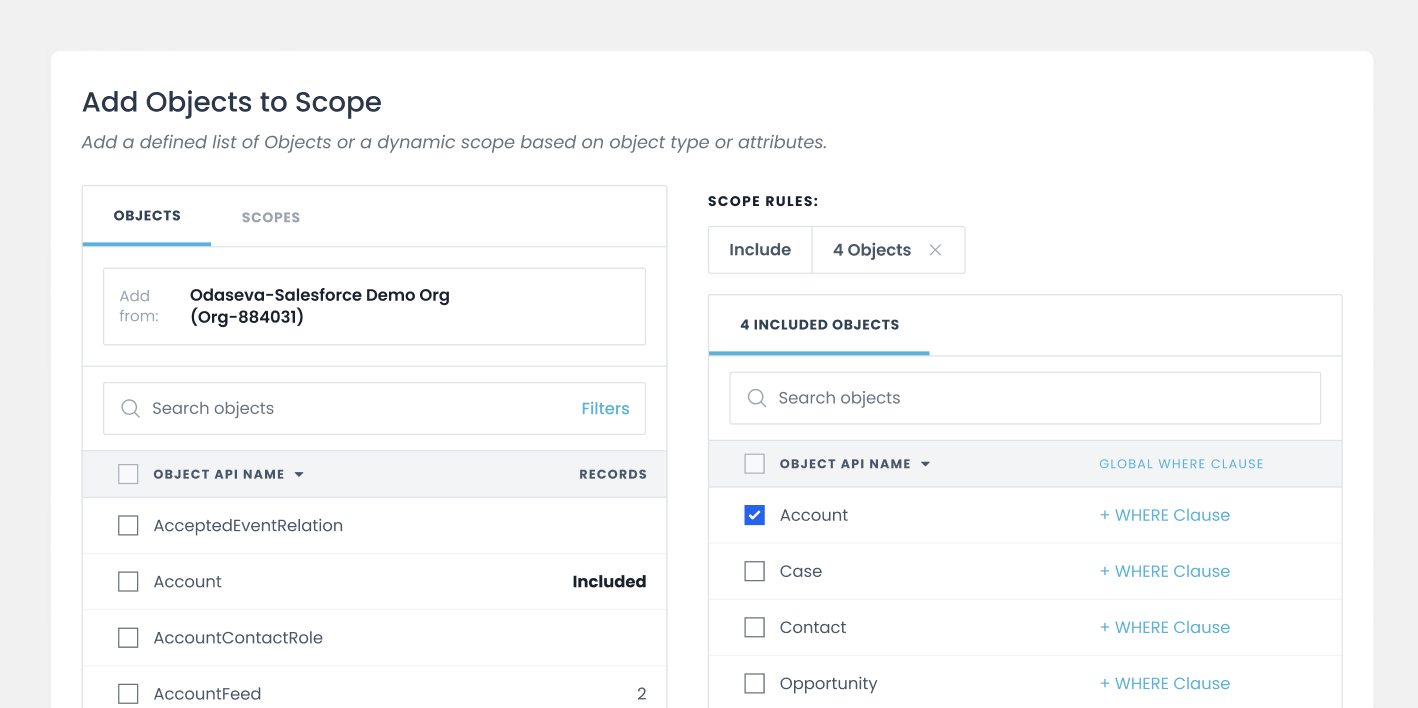
Power Salesforce Data for Autonomous Innovation.
Empower analytics teams with autonomous, secure access to Salesforce data. Data sharing remains strictly controlled, without impacting production performance or stability..
Enforce Trust, Power Data Innovation
Protect customer data by eliminating unnecessary copies. Maintain control with Zero Trust security and flexible regional data residency options on AWS.
FAQs

Traditional ETL demands complex pipeline engineering, whereas Odaseva provides a managed service that autonomously handles orchestration, Change Data Capture (CDC), schema drift, and API failure recovery.
While more modern Zero Copy solutions are emerging, they lack the low latency, historical depth, and massive scalability required to activate the full customer context for deep analytics and trusted AI.
Hours, not months. Because ETL coding is no longer needed, Salesforce objects can be activated into Redshift instantly. In addition, our high-throughput architecture allows us to load hundreds of millions of records per hour to ensure immediate analytical readiness for the largest Orgs.
No. Odaseva delivers a managed data product. We handle the schema uniformization and orchestration autonomously. Your authorized data analysts and scientists can then instantly access raw data as a self service. Those tables also provide a robust, consistent "bronze layer" that data engineers can further refine and orchestrate as part of broader data pipelines.
No. This is a fundamental advantage of our architecture. By uniquely repurposing your data protection streams (backups and archives), we activate data with zero additional calls to the production Orgs and API for consumption. This decouples your Redshift analytical workloads from your CRM ensuring heavy AI queries never degrade performance for your operations.
Other solutions charge by credits per query or per million records, creating financial roadblocks that discourage AI exploration and analytics scaling. Odaseva uses a flat-fee model based on the Salesforce Org scope. You can activate any Salesforce object at any time and reuse that data limitlessly across every Redshift cluster, SageMaker notebook, and AI agent in your AWS environment.
The Odaseva platform is natively hosted on AWS, ensuring that your Salesforce backups and Zero Copy data shares remain within your trusted, encrypted and highly secured AWS environment. Data is maintained in its original, secured environment for simplified data governance. Using Amazon Redshift Datashares, you can then deliver Salesforce data as a service across your organization, while eliminating exposure risks through end-to-end encryption and native AWS KMS integration. Data sharing is read-only and there is no data being copied or moved over into your own AWS storage.
Key resources
Empowering Scalable, AI-ready Data Ecosystems with Odaseva Data Edge

Modern Architecture for Data at Speed and High Availability

3 Steps to Secure Your Data in an AI-Automated World


